Week 7: Introduction to Spark
DSAN 6000: Big Data and Cloud Computing
Fall 2026
Class Sessions
Big Midterm \(\rightarrow\) Final Project Updates
Pre-Approved Final Project Datasets!
See here
Practice Midterm
- Pick one of the pre-approved datasets
- Read the corresponding vignette on the website
- Answer each practice question based on this vignette
Vignettes will also be provided on the paper midterm!
Entering Our Spark Era
| PySpark |
 Written in |
 Compiles to |
 Java Virtual Machine (JVM) |
Roadmap
(Logistical point: Form for new AWS Canvas accounts)
- Week 3: Map-Reduce \(\leadsto\) Last Week: Athena with AWS Glue under the hood for “automated” ETL!
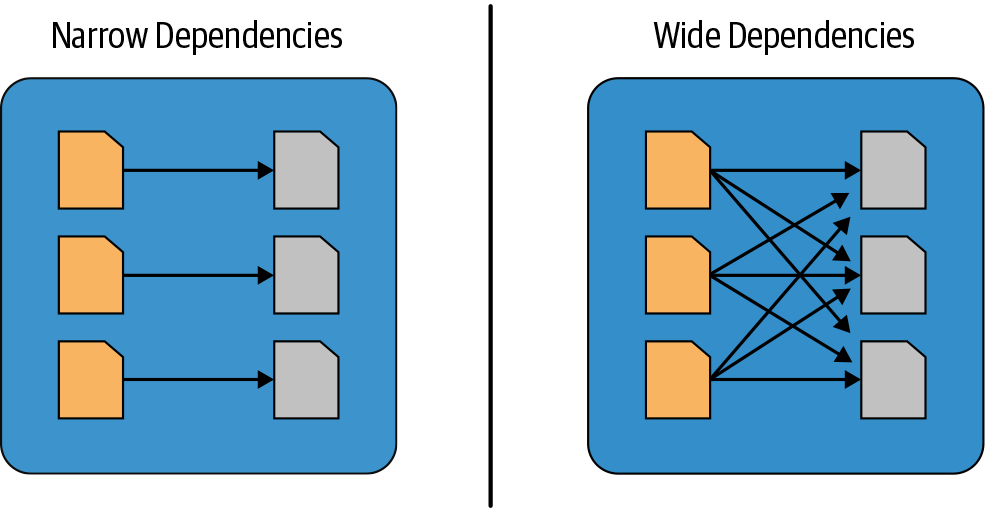
- This Week: Hitting a wall with Athena… It doesn’t know in advance what [types of] queries you’re going to make!
- If you’re going to group by (e.g.) state, then rent 50 computers to process one state each, Athena doesn’t know to place the Ohio data on the Ohio computer!
- Hadoop MapReduce: Allows “steering” of Map-Reduced data-computation pairing
Your Goal: Narrow Dependencies!
References
Damji, Jules S., Brooke Wenig, Tathagata Das, and Denny Lee. 2020. Learning Spark. O’Reilly Media, Inc.