Week 3: Separating Data from Computation for Parallel Processing

DSAN 6000: Big Data and Cloud Computing
Fall 2026

Jeff Jacobs

jj1088@georgetown.edu

Monday, September 14, 2026

Parallelization in General

Fig 1: DJ Kentaro = The Scheduler, Spinning records = Processes

Quick Survey Question, for Intuition-Building

  • Is the human sensorimotor system capable of “true” multitasking?
  • As in, doing two things at the exact same time?
  • (…Or, do we instead have to rapidly switch back and forth between tasks?)

The Answer

  • The human brain is [mostly] not capable of true multitasking (rare exceptions)
  • In CS terms, true multitasking is called multiprocessing (more on this later)
  • We are capable, however, of other modes of concurrency:
Multithreading Asynchronous Execution
Unconsciously
(you do it already, “naturally”)
Focus on one speaker within a loud room, many other sounds entering your ears Put food in oven, set alarm, go do something else, take out of oven once alarm goes off
Consciously
(you can do it with effort/practice)
Pat head (up and down) and rub stomach (circular motion) “simultaneously” Throw a ball in the air, clap 3 times, catch ball
From Observer’s Perspective? Looks like multiprocessing Doesn't look like multiprocessing

Helpful Specifically for Programming

  • Course notes from MIT’s class on parallel computing phrases it like: if implemented thoughtfully, concurrency is a power multiplier for your code (do 10 things in 1 second instead of 10 seconds)
Helpful In General as a Way of Thinking!

  • Say you get hired as a Project Manager…
  • Part of your job will fundamentally involve pipelines!
    • Need to know when Task \(B\) does/does not require Task \(A\) as a prerequisite
    • Need to know whether Task \(A\) and Task \(B\) can share one resource or need their own individual resources
    • Once Task \(A\) and \(B\) both complete, how do we merge their results together?

Avoiding the Rabbithole

Parallel computing is a rabbithole, but one you can safely avoid via simple heuristics (“rules of thumb”):

  1. Check for optimizations to serial code first (vectorization, memoization),
  2. Check for embarrassingly parallel code blocks
  3. Use map-reduce approach for more complicated cases
  4. Still hitting a wall? Try horizontal scaling

…Horizontally-scaled map-reduce, you say? Why, that’s exactly what Hadoop / Spark do for us!

“Embarrassingly Parallel” Pipelines

Embarrassingly Parallel

A problem is embarrassingly parallel when it can be divided into \(N\) subtasks without any temporal dependence or need for communication between the tasks

Temporal Dependence:

Does spongebob have to wait for one krabby patty to finish cooking before starting to cook a second one?

Between-Process Communication:

Does the cooking of one patty require some piece of another partially-cooked patty?

Naïvely “Chopping” Non-Embarrassingly-Parallel Problems

  • Not all data-processing pipelines are embarrassingly-parallel!
  • May still be hope via map-reduce approach
  • We’ll use the following terminology:

Non-Embarrassingly-Parallel Problems

If a data-processing problem is not embarrassingly-parallel, then the tasks that need to be performed may be:

  • Loosely-coupled: Can be mapped to embarrassingly-parallel pieces, solved separately by non-communicating processors, then merged
  • Tightly-coupled: Can be mapped to sub-tasks, solved separately by communicating processors, then merged
  • Non-parallelizable: \(\text{P}\)-complete” problems proven to have no efficient parallelization unless \(\text{P} = \text{NP}\)
Buzzkill: Complications to Come 😰

If it’s such a magical powerup, why not parallelize everything? A: Overhead costs 😞

Embarrassingly Parallel Loosely Coupled Tightly Coupled
Sending tasks to workers ⏱️ ⏱️ ⏱️
Facilitating communication between workers ⏱️
Collecting results from workers ⏱️ ⏱️
Merging collected results ⏱️ ⏱️
  • Map-reduce (underlying Hadoop / Spark) focuses on loosely-coupled problems (may be overkill for embarrassingly-parallel: can just use multiprocessing or joblib)
  • Earlier famous parallelization library was created for tightly-coupled problems: Message Passing Interface (C, C++, and Fortran)

In Action

import time
from sympy.ntheory import factorint
from joblib import Parallel, delayed
parallel_runner = Parallel(n_jobs=4)
start, end = 500, 650
def find_prime_factors(num):
  time.sleep(.01)
  return factorint(num, multiple=True)
disp_time = lambda start, end: print('{:.4f} s'.format(end - start))
serial_start = time.time()
result = [
  (i,find_prime_factors(i))
  for i in range(start, end+1)
]
serial_end = time.time()
disp_time(serial_start, serial_end)
1.7994 s
par_start = time.time()
result = parallel_runner(
  delayed(find_prime_factors)(i)
  for i in range(start, end+1)
)
par_end = time.time()
disp_time(par_start, par_end)
0.8214 s

What Is joblib Doing Here?

Input
1 500
2 501
3 502
4 503
5 504
\(\vdots\)
151 650

joblib / Hadoop / Spark

Worker
1
2
3
4

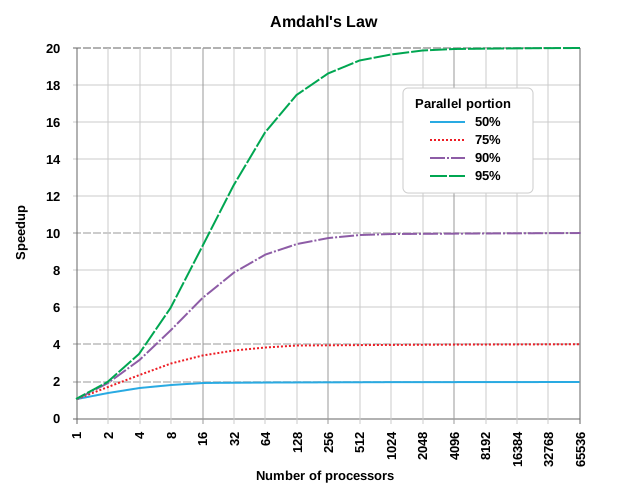
Amdahl’s Law

How do we know whether or not the overhead is “worth it”?
Beyond Embarrassingly-Parallel Problems…

  • Why “map”-reduce? What does it mean to map non-embarrassingly-parallel tasks to embarrassingly-parallel ones?

What Happens When Not Embarrassingly Parallel?

  • Think of the difference between linear and quadratic equations in algebra:
  • \(3x - 1 = 0\) is “embarrassingly” solvable, on its own: you can solve it directly, by adding 3 to both sides \(\implies x = \frac{1}{3}\). Same for \(2x + 3 = 0 \implies x = -\frac{3}{2}\)
  • Now consider \(6x^2 + 7x - 3 = 0\): Harder to solve “directly”, so your instinct might be to turn to the laborious quadratic equation:

\[ \begin{align*} x = \frac{-b \pm \sqrt{b^2 - 4ac}}{2a} = \frac{-7 \pm \sqrt{49 - 4(6)(-3)}}{2(6)} = \frac{-7 \pm 11}{12} = \left\{\frac{1}{3},-\frac{3}{2}\right\} \end{align*} \]

  • And yet, \(6x^2 + 7x - 3 = (3x - 1)(2x + 3)\), meaning that we could have split the problem into two “embarrassingly” solvable pieces, then multiplied to get result!

The Analogy to Map-Reduce

\(\leadsto\) If code is not embarrassingly parallel (instinctually requiring laborious serial execution), \(\underbrace{6x^2 + 7x - 3 = 0}_{\text{Solve using Quadratic Eqn}}\)
But can be split into… \((3x - 1)(2x + 3) = 0\)
Embarrassingly parallel pieces which combine to same result, \(\underbrace{3x - 1 = 0}_{\text{Solve directly}}, \underbrace{2x + 3 = 0}_{\text{Solve directly}}\)
We can use map-reduce to achieve ultra speedup (running “pieces” on GPU!) \(\underbrace{(3x-1)(2x+3) = 0}_{\text{Solutions satisfy this product}}\)

For a Problem You’ve Seen Before!

  • Problem from DSAN 5000/5100: Computing SSR (Sum of Squared Residuals)

  • \(y = (1,3,2), \widehat{y} = (2, 5, 0) \implies \text{SSR} = (1-2)^2 + (3-5)^2 + (2-0)^2 = 9\)

  • Computing pieces separately:

    map(do_something_with_piece, list_of_pieces)
    my_map = map(lambda input: input**2, [(1-2), (3-5), (2-0)])
    map_result = list(my_map)
    map_result
    [1, 4, 4]
  • Combining solved pieces

    reduce(how_to_combine_pair_of_pieces, pieces_to_combine)
    from functools import reduce
    my_reduce = reduce(lambda piece1, piece2: piece1 + piece2, map_result)
    my_reduce
    9

Quick Aside: Functional Programming (FP)

Functions vs. Functionals

You may have noticed: map() and reduce() are “meta-functions”: functions that take other functions as inputs

def add_5(num):
  return num + 5
add_5(10)
15
def apply_twice(fn, arg):
  return fn(fn(arg))
apply_twice(add_5, 10)
20

In Python, functions can be used as vars (Hence lambda):

add_5 = lambda num: num + 5
apply_twice(add_5, 10)
20

This relates to a whole paradigm, “functional programming”: mostly outside scope of course, but lots of important+useful takeaways/rules-of-thumb!

Train Your Brain for Functional Approach \(\implies\) Master Debugging!

  • In CS Theory: enables formal proofs of correctness

  • In CS practice:

    When a program doesn’t work, each function is an interface point where you can check that the data are correct. You can look at the intermediate inputs and outputs to quickly isolate the function that’s responsible for a bug.
    (from Python’s “Functional Programming HowTo”)

Code \(\rightarrow\) Pipelines \(\rightarrow\) Debuggable Pipelines

  • Scenario: Run code, check the output, and… it’s wrong 😵 what do you do?
  • Usual approach: Read lines one-by-one, figuring out what they do, seeing if something pops out that seems wrong; adding comments like # Convert to lowercase
  • Easy case: found typo in punctuation removal code. Fix the error, add comment like # Remove punctuation

    Rule 1 of FP: transform these comments into function names

  • Hard case: Something in load_text() modifies a variable that later on breaks remove_punct() (Called a side-effect)

    Rule 2 of FP: NO SIDE-EFFECTS!

G input in.txt load_text load_text (Verb) input->load_text lowercase lowercase (Verb) load_text->lowercase 🧐 ✅ remove_punct remove_punct (Verb) lowercase->remove_punct 🧐 ✅ remove_stopwords remove_stopwords (Verb) remove_punct->remove_stopwords 🧐 ❌❗️ output out.txt remove_stopwords->output

(Does this way of diagramming a program look familiar?)

  • With side effects: ❌ \(\implies\) issue is somewhere earlier in the chain 😩🏃‍♂️
  • No side effects: ❌ \(\implies\) issue must be in remove_punct()!!! 😎 ⏱️ = 💰

If It’s So Useful, Why Doesn’t Everyone Do It?

  • Trapped in imperative (sequential) coding mode: Path dependency / QWERTY
  • We need to start thinking like this bc, 1000x harder to debug parallel code! So we need to be less ad hoc in how we write+debug, from here on out! 🙇‍♂️🙏

From Leskovec, Rajaraman, and Ullman (2014)

But… Why is All This Weird Mapping and Reducing Necessary?

  • Without knowing a bit more of the internals of computing efficiency, it may seem like a huge cost in terms of overly-complicated overhead, not to mention learning curve…

The “Killer Application”: Matrix Multiplication

From Leskovec, Rajaraman, and Ullman (2014), which is (legally) free online!

The Killer Way-To-Learn: Text Counts!

  • (2014): Text counts (2.2) \(\rightarrow\) Matrix multiplication (2.3) \(\rightarrow \cdots \rightarrow\) PageRank (5.1)
  • The goal: User searches “Denzel Curry”… How relevant is a given webpage?
  • Scenario 1: Entire internet fits on CPU \(\implies\) We can just make a big dict:

G internet Scan in O(n): Today Denzel Washington ate a big bowl of Yum's curry. Denzel allegedly rubbed his tum and said "yum yum yum" when he tasted today's curry. "Yum! It is me Denzel, curry is my fav!", he exclaimed. According to his friend Steph, curry is indeed Denzel's fav. We are live with Del Curry in Washington for a Denzel curry update. ccounts Overall Counts ('according',1) ('allegedly',1) ('ate',1) ('big',1) ('bowl',1) ('curry',6) ('del',1) ('denzel',5) ('exclaimed',1) ('fav',2) ('friend',1) ('indeed',1) ('live',1) ('rubbed',1) ('said',1) ('steph',1) ('tasted',1) ('today',2) ('tum',1) ('update',1) ('washington',2) ('yum',4) internet->ccounts Loop Over Words

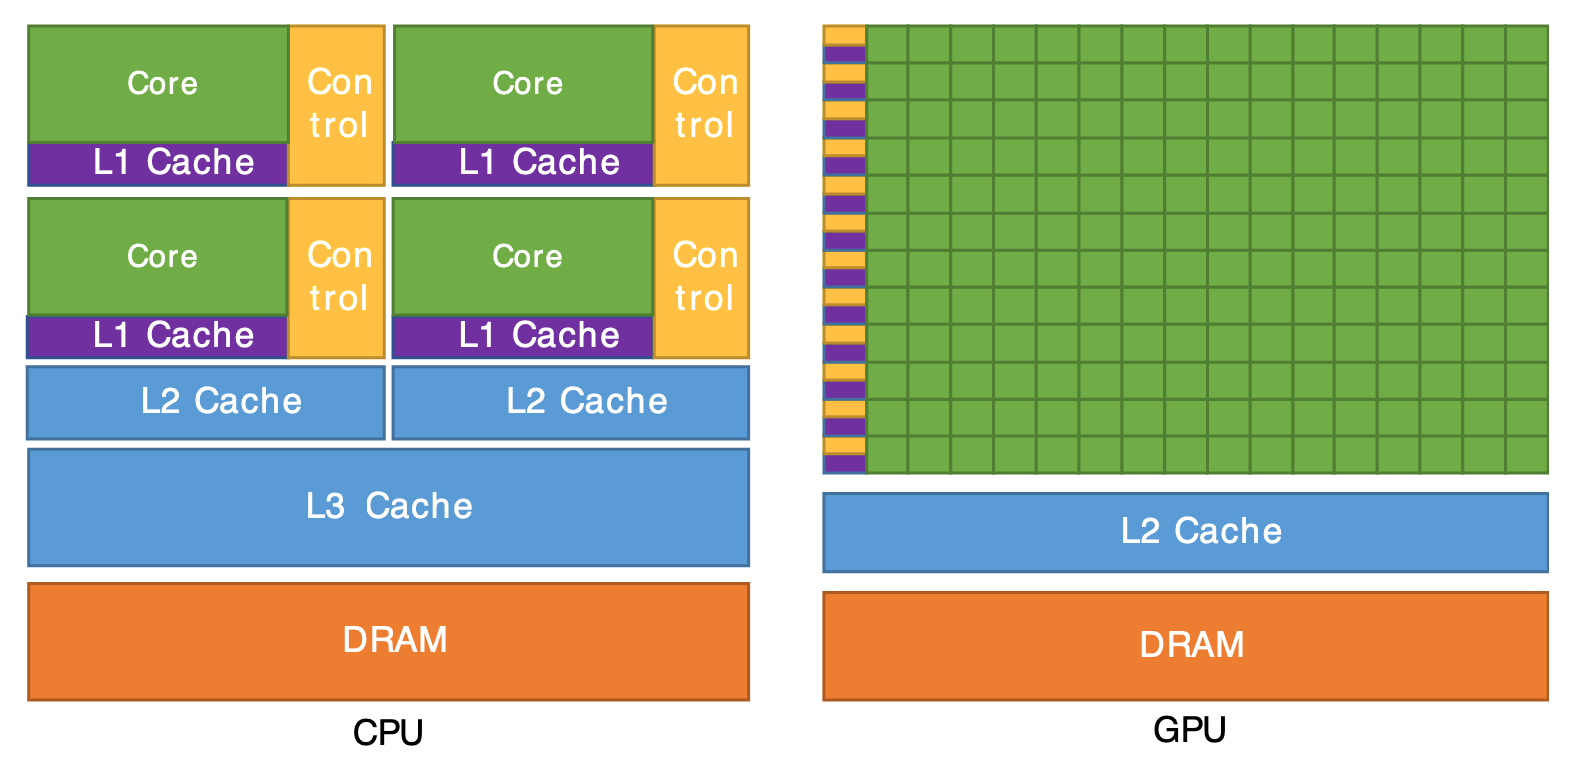
If Everything Doesn’t Fit on CPU…

From Cornell Virtual Workshop, “Understanding GPU Architecture”

Break Problem into Chunks for the Green Bois!

G chunked Chunked Document Today Denzel Washington ate a big bowl of Yum's curry. Denzel allegedly rubbed his tum and said "yum yum yum" when he tasted today's curry. "Yum! It is me Denzel, curry is my fav!", he exclaimed. According to his friend Steph, curry is indeed Denzel's fav. We are live with Del Curry in Washington for a Denzel curry update. chcounts Chunked Counts ('today',1) ('denzel',1) ... ('tum',1) ('said',1) ('yum',1) ('yum',1) ('yum',1) ... ('fav',1) ('exclaimed',1) ... ('del',1) ('curry',1) ('washington',1) ('denzel',1) ('curry',1) ('update',1) chunked:p1->chcounts:p1 O(n/4) chunked:p2->chcounts:p2 O(n/4) chunked:p3->chcounts:p3 O(n/4) chunked:p4->chcounts:p4 O(n/4) scounts Hashed Counts ('allegedly',1) ... ('curry',1) ('denzel',2) ... ('yum',1) ('curry',2) ('denzel',1) ... ('yum',4) ('according',1) ('curry',1) ('del',1) ('denzel',1) ... ('curry',2) ('denzel',1) ('update',1) ('washington',1) chcounts:p1->scounts:p1 O(n/4) chcounts:p2->scounts:p2 O(n/4) chcounts:p3->scounts:p3 O(n/4) chcounts:p4->scounts:p4 O(n/4) ccounts Overall Counts ('according',1) ('allegedly',1) ('ate',1) ('big',1) ('bowl',1) ('curry',6) ('del',1) ('denzel',5) ('exclaimed',1) ('fav',2) ('friend',1) ('indeed',1) ('live',1) ('rubbed',1) ('said',1) ('steph',1) ('tasted',1) ('today',2) ('tum',1) ('update',1) ('washington',2) ('yum',4) scounts:p1->ccounts:p1 scounts:p2->ccounts:p1 scounts:p3->ccounts:p1 scounts:p4->ccounts:p1 scounts:p2->ccounts Merge in O(n)

  • \(\implies\) Total = \(O(3n) = O(n)\)
  • But also optimized in terms of constants, because of sequential memory reads

Lab Time!

Lab 3: Python’s multiprocessing library

References

Leskovec, Jure, Anand Rajaraman, and Jeffrey David Ullman. 2014. Mining of Massive Datasets. Cambridge University Press.